The most downloaded AI models that fit on your GPU
Most "best models for your GPU" lists are somebody's opinion. This one is two measurements: how many people downloaded a model from Hugging Face in the last 30 days, and whether a real file of it fits in your card's memory with room left for a conversation.
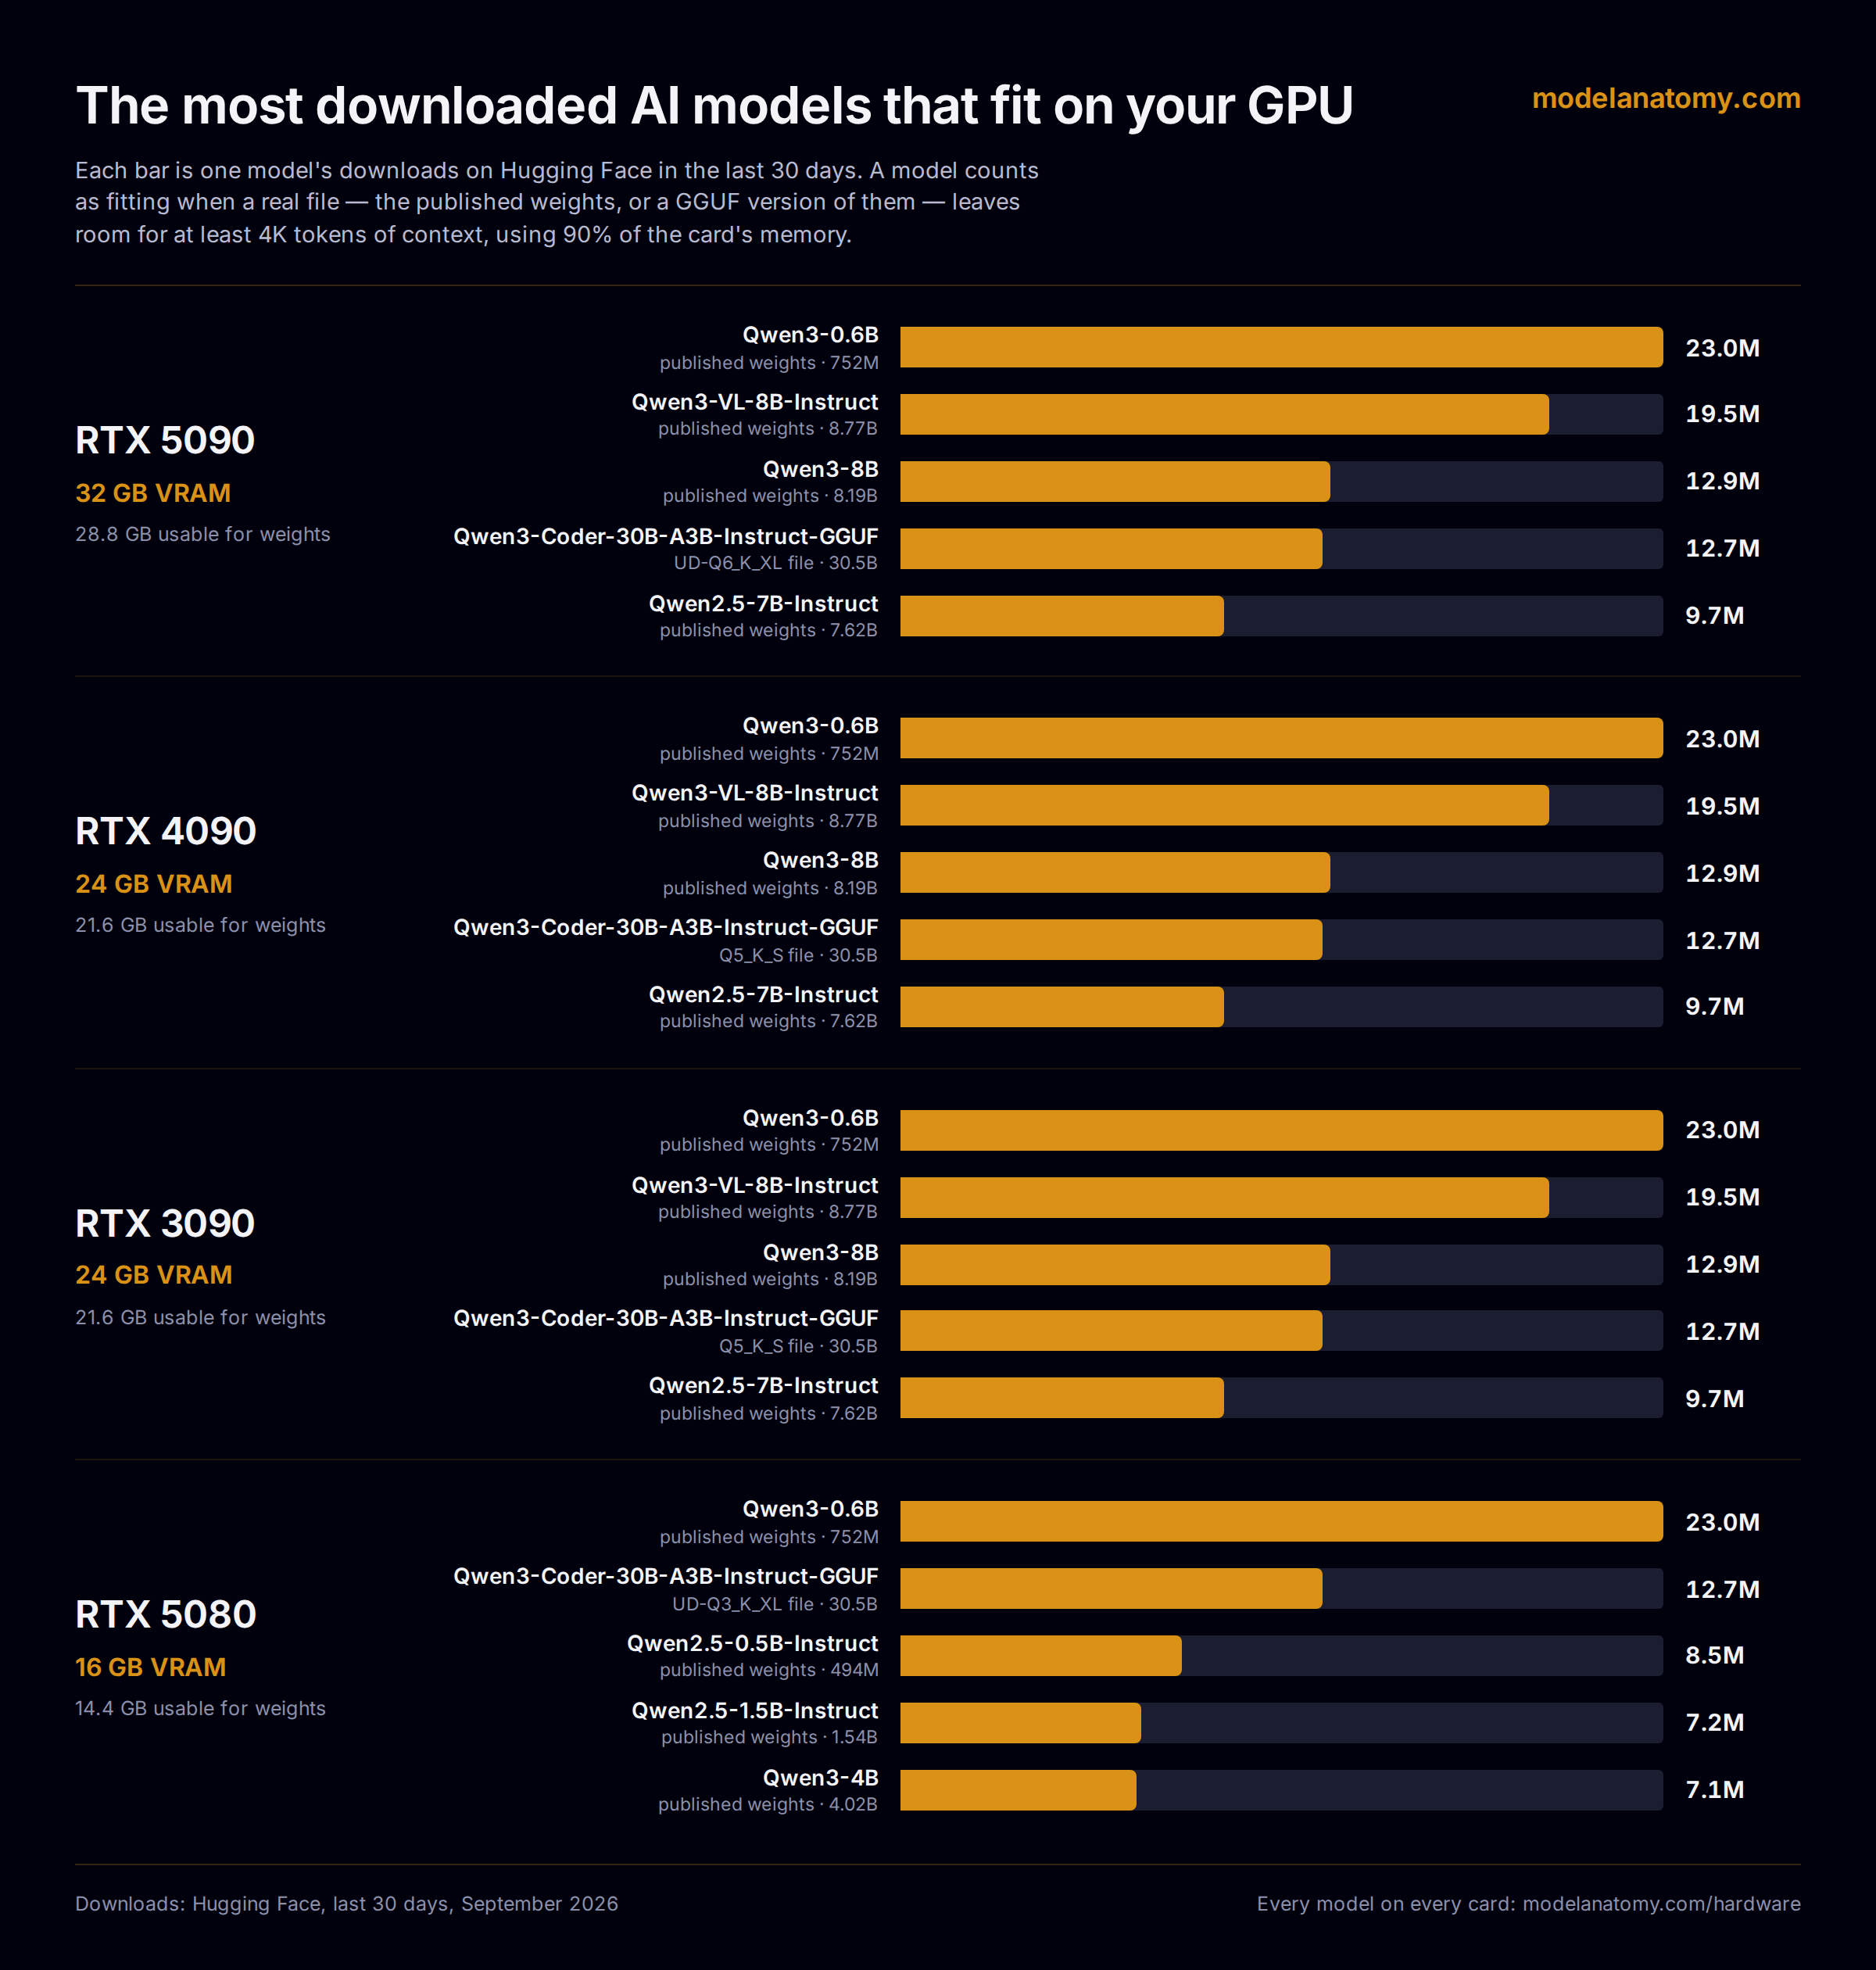
The first thing the chart shows is that the popular models fit almost anything. Qwen3-0.6B, Qwen3-VL-8B and Qwen3-8B are near the top for the 5090, the 4090 and the 3090 alike, because downloads are dominated by small models that people fine-tune, embed in apps and run on laptops.
The second thing is where the cards actually differ: the file. Qwen3-Coder-30B is on every list, but a 5090
runs it at UD-Q6_K_XL, a 4090 at Q5_K_S and a 5080 at UD-IQ3_XXS. Same model, three levels of
compression — see what bits per weight means below.
RTX 5090 — 32 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| Qwen/Qwen3-0.6B | 752M | As published | full 40K |
| Qwen/Qwen3-VL-8B-Instruct | 8.77B | As published | ≈ 75K |
| trl-internal-testing/tiny-Qwen2ForCausalLM-2.5 | 2.44M | As published | full 32K |
| Qwen/Qwen3-8B | 8.19B | As published | full 40K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | UD-Q6_K_XL | ≈ 24K |
| google/gemma-4-26B-A4B-it | 25.8B | 4-bit (estimate) | full 256K |
| Qwen/Qwen3.6-35B-A3B-FP8 | 36.0B | 4-bit (estimate) | full 256K |
| Qwen/Qwen2.5-7B-Instruct | 7.62B | As published | full 32K |
| Qwen/Qwen3.5-9B | 9.65B | As published | full 256K |
| google/gemma-4-31B-it | 31.3B | 4-bit (estimate) | ≈ 62K |
203 models the site has analyzed fit on an RTX 5090 with at least 8K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 4090 — 24 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| Qwen/Qwen3-0.6B | 752M | As published | full 40K |
| Qwen/Qwen3-VL-8B-Instruct | 8.77B | As published | ≈ 27K |
| trl-internal-testing/tiny-Qwen2ForCausalLM-2.5 | 2.44M | As published | full 32K |
| Qwen/Qwen3-8B | 8.19B | As published | ≈ 35K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | Q4_1 | ≈ 24K |
| google/gemma-4-26B-A4B-it | 25.8B | 4-bit (estimate) | ≈ 164K |
| Qwen/Qwen3.6-35B-A3B-FP8 | 36.0B | 4-bit (estimate) | ≈ 63K |
| Qwen/Qwen2.5-7B-Instruct | 7.62B | As published | full 32K |
| Qwen/Qwen3.5-9B | 9.65B | As published | ≈ 67K |
| google/gemma-4-31B-it | 31.3B | 4-bit (estimate) | ≈ 19K |
200 models the site has analyzed fit on an RTX 4090 with at least 8K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 3090 — 24 GB
The 3090 holds exactly what the 4090 holds: the same 24 GB, so the same files fit. It generates more slowly, because its memory is slower, but nothing here changes.
| Model | Params | File that fits | Context |
|---|---|---|---|
| Qwen/Qwen3-0.6B | 752M | As published | full 40K |
| Qwen/Qwen3-VL-8B-Instruct | 8.77B | As published | ≈ 27K |
| trl-internal-testing/tiny-Qwen2ForCausalLM-2.5 | 2.44M | As published | full 32K |
| Qwen/Qwen3-8B | 8.19B | As published | ≈ 35K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | Q4_1 | ≈ 24K |
| google/gemma-4-26B-A4B-it | 25.8B | 4-bit (estimate) | ≈ 164K |
| Qwen/Qwen3.6-35B-A3B-FP8 | 36.0B | 4-bit (estimate) | ≈ 63K |
| Qwen/Qwen2.5-7B-Instruct | 7.62B | As published | full 32K |
| Qwen/Qwen3.5-9B | 9.65B | As published | ≈ 67K |
| google/gemma-4-31B-it | 31.3B | 4-bit (estimate) | ≈ 19K |
200 models the site has analyzed fit on an RTX 3090 with at least 8K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 5080 — 16 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| Qwen/Qwen3-0.6B | 752M | As published | full 40K |
| Qwen/Qwen3-VL-8B-Instruct | 8.77B | 4-bit (estimate) | ≈ 63K |
| trl-internal-testing/tiny-Qwen2ForCausalLM-2.5 | 2.44M | As published | full 32K |
| Qwen/Qwen3-8B | 8.19B | 4-bit (estimate) | full 40K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | Q3_K_S | ≈ 11K |
| Qwen/Qwen2.5-7B-Instruct | 7.62B | 4-bit (estimate) | full 32K |
| Qwen/Qwen3.5-9B | 9.65B | UD-Q8_K_XL | ≈ 41K |
| Qwen/Qwen2.5-0.5B-Instruct | 494M | As published | full 32K |
| Qwen/Qwen2.5-1.5B-Instruct | 1.54B | As published | full 32K |
| Qwen/Qwen3-4B | 4.02B | As published | full 40K |
137 models the site has analyzed fit on an RTX 5080 with at least 8K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
What "fits" means
A model fits when a real file of it — the published weights, or a GGUF version somebody made — leaves room for at least 8K tokens of context in the tables above, using about 90% of the card's memory. The rest goes to the driver and the program running the model.
Two things the tables deliberately don't do. They don't count files that would only fit as a hypothetical 4-bit conversion nobody has published, so everything listed is something you can download today. And "best" means popular and fits, not good: the site measures what a model needs, never how well it answers.
Each model name opens its page, where you can see where its parameters live, what it needs at a datacentre, and the exact command to download it.
Related
- Best AI models for a 24 GB GPU (RTX 4090, RTX 3090)
- Best AI models for an 8 GB GPU (RTX 4060, RTX 5060)
- The largest AI models that fit on your GPU
- Which AI models can I run on my GPU? — every card, including Macs and data-centre GPUs