The largest AI models that fit on your GPU
Ask how large a model your graphics card can run and the honest answer has two halves: every consumer card stops at roughly the same size, and what changes is how much of the model survives.
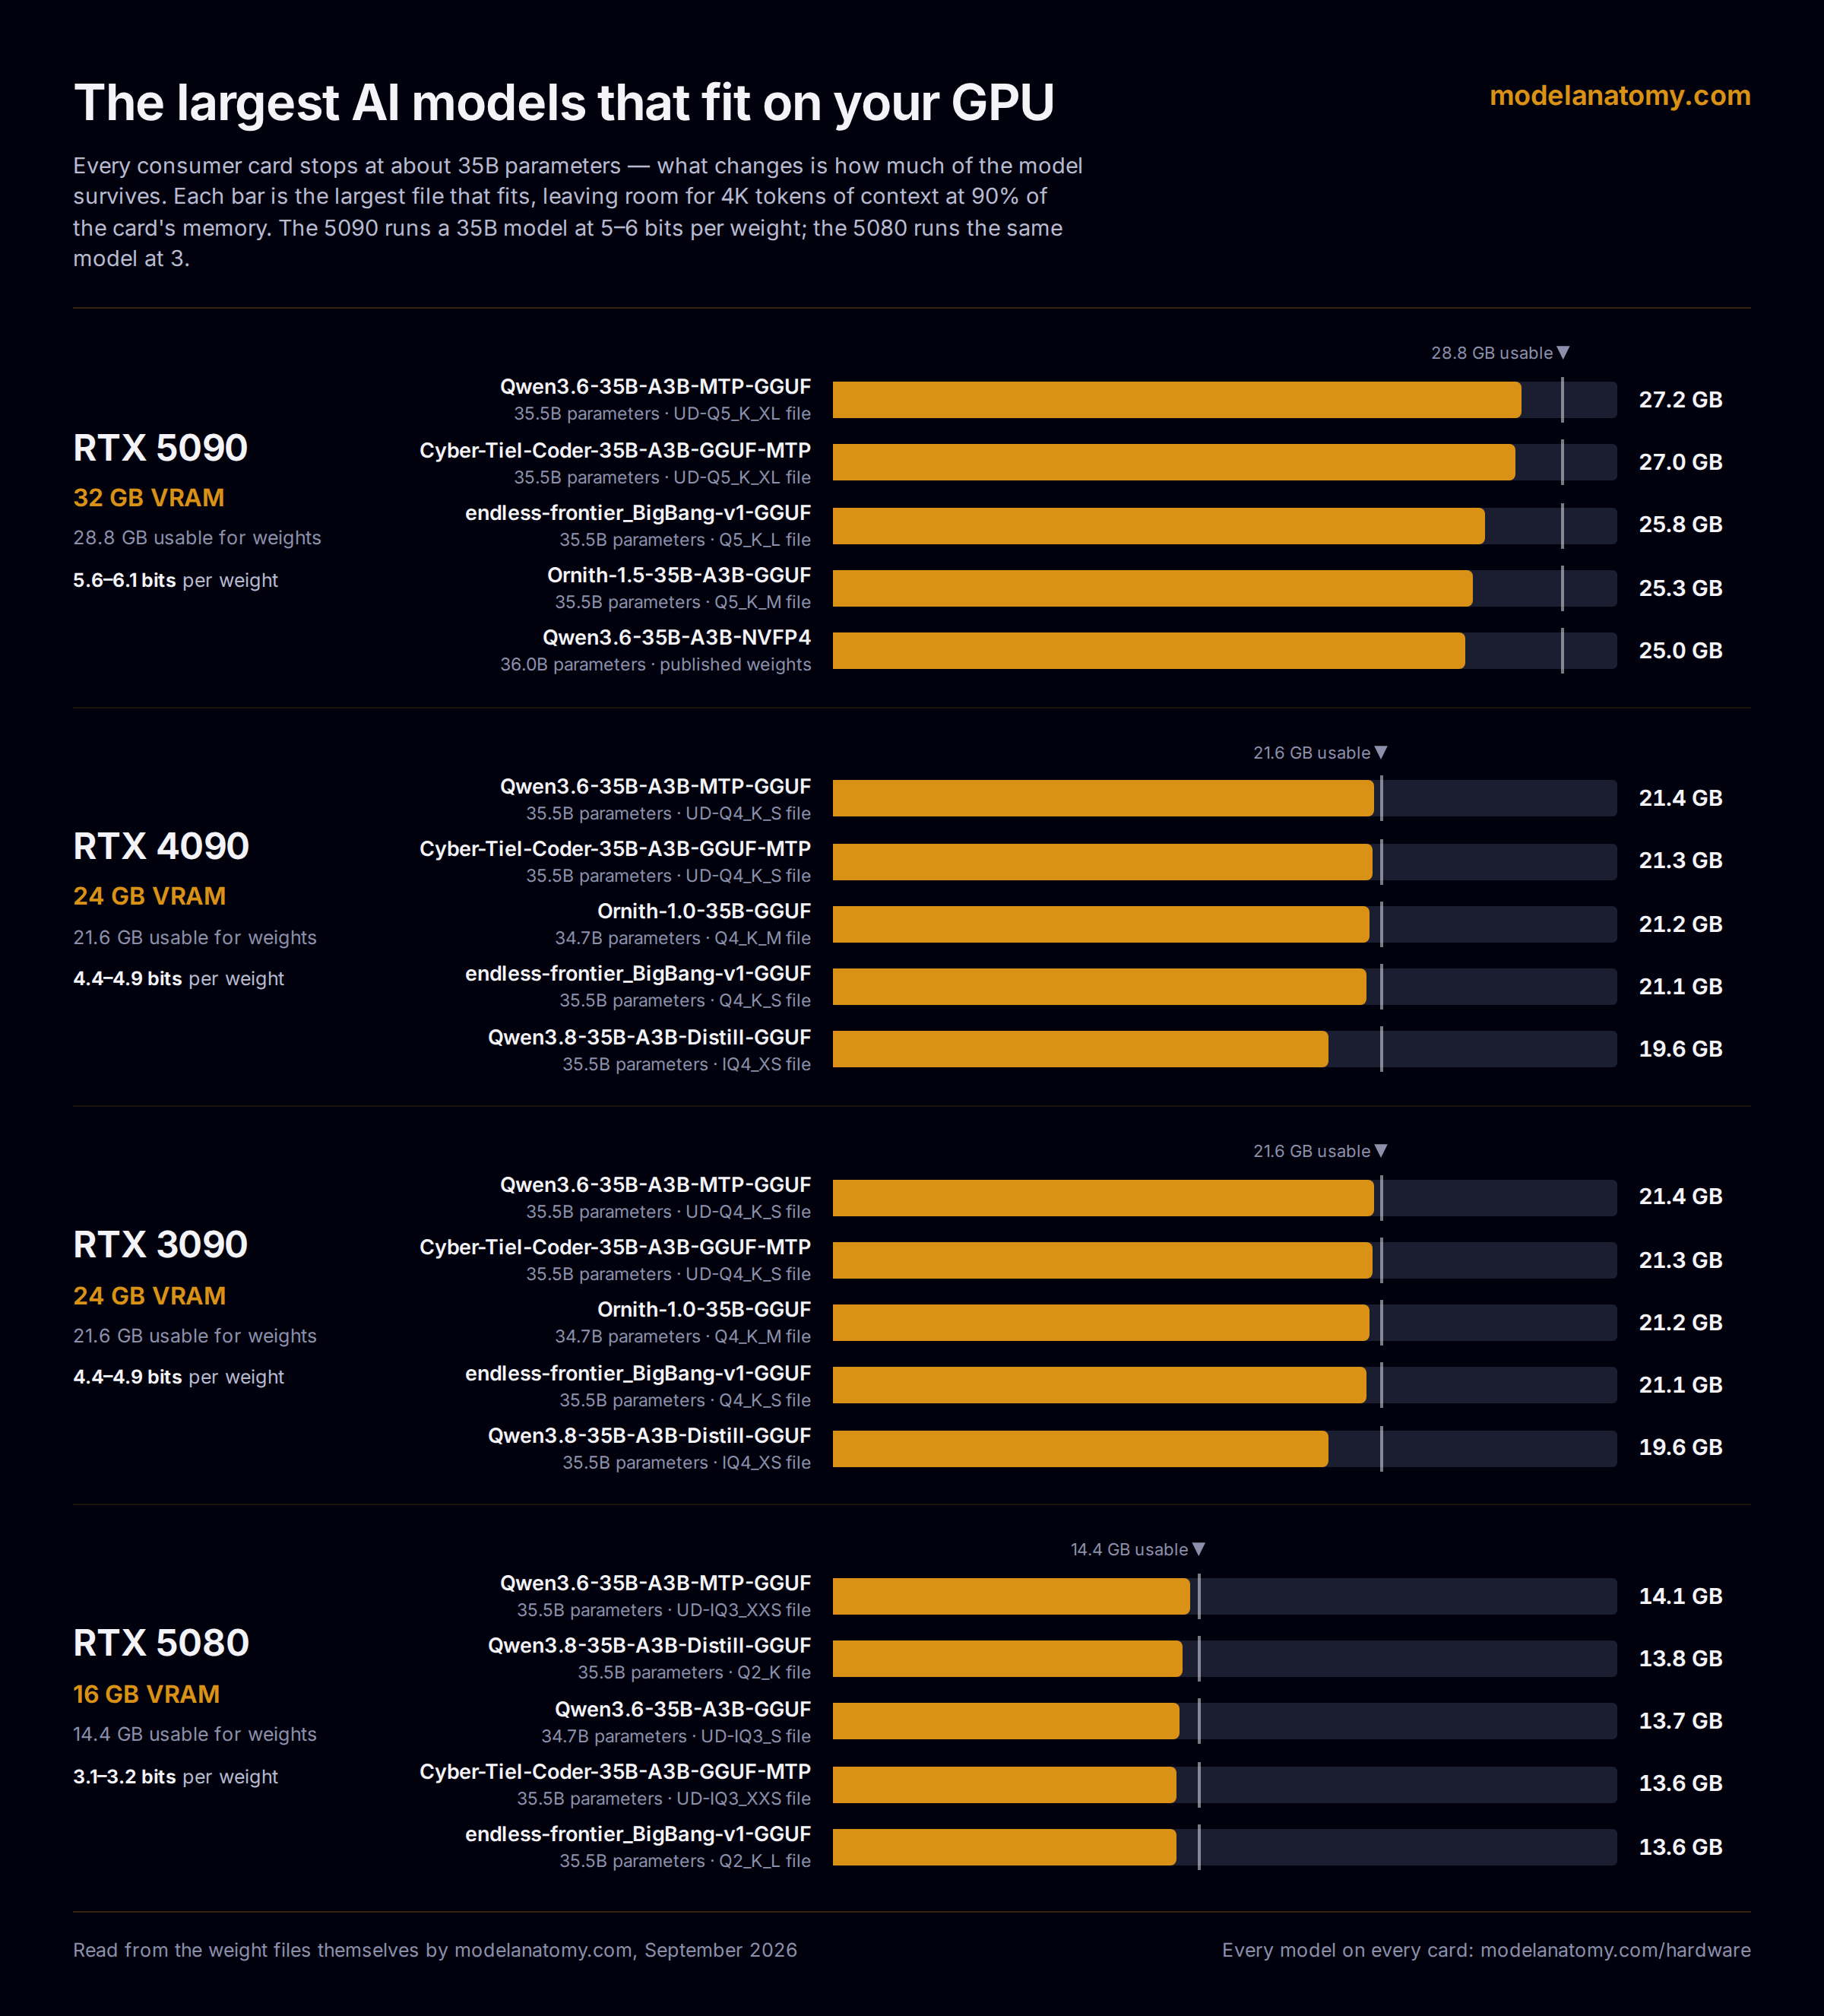
All four cards top out around 35 billion parameters, because that is where today's popular mixture-of-experts models sit. What separates a 32 GB card from a 16 GB one is the number of bits each weight gets:
| Card | Usable | A 35B model arrives as | Bits per weight |
|---|---|---|---|
| RTX 5090 | 28.8 GB | ~27 GB, UD-Q5_K_XL |
5.6–6.1 |
| RTX 4090 | 21.6 GB | ~21 GB, UD-Q4_K_S |
4.4–4.9 |
| RTX 3090 | 21.6 GB | ~21 GB, UD-Q4_K_S |
4.4–4.9 |
| RTX 5080 | 14.4 GB | ~14 GB, UD-IQ3_XXS |
3.1–3.2 |
What bits per weight means
A model is a pile of numbers, published at 16 bits each. Quantizing rounds them into smaller slots: 4-bit quantization stores each weight in about half a byte, plus small scale factors that let the runtime reconstruct each block — which is why the real figure lands on 4.8 rather than exactly 4.
Down to about 4 bits the loss is mild and most people never notice it. At 3 bits it shows: more repetition, weaker reasoning, worse code. Below that, models degrade badly. So a 16 GB card can load a 35B model — it is running a more damaged copy than a 32 GB card is, and often a smaller model at 5 bits is the better trade.
The file names encode the scheme: Q4 is the nominal width, _K spends more bits on the parts that matter most,
_S/_M/_L/_XL are variants of that trade, IQ squeezes lower with a smarter codebook, and UD- is
Unsloth's dynamic mix.
The biggest models each card can hold
Largest download first, as in the chart, with at least 4K tokens of context left over. Note that the biggest file is not always the biggest model: a 35B model at 3 bits is a smaller download than a 14B one at 8.
RTX 5090 — 32 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| ornith-ai/Ornith-1.0-35B-GGUF | 34.7B | Q6_K | ≈ 11K |
| HauhauCS/Qwen3.6-35B-A3B-Uncensored-HauhauCS-Aggressive | 34.7B | Q5_K | ≈ 34K |
| huihui-ai/Huihui-Qwen3.8-27B-abliterated-GGUF | 27.3B | Q8_K_L | ≈ 21K |
| unsloth/Qwen3.6-35B-A3B-MTP-GGUF | 35.5B | UD-Q5_K_XL | ≈ 75K |
| peculiar-ragdoll/Cyber-Tiel-Coder-35B-A3B-GGUF-MTP | 35.5B | UD-Q5_K_XL | ≈ 84K |
| peculiar-ragdoll/Tiel-Coder-35B-A3B-GGUF | 34.7B | UD-Q5_K_XL | ≈ 102K |
| unsloth/Qwen3.6-35B-A3B-GGUF | 34.7B | UD-Q5_K_XL | ≈ 102K |
| unsloth/Qwen3.6-35B-A3B-NVFP4 | 36.0B | As published | ≈ 108K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | UD-Q6_K_XL | ≈ 24K |
| unsloth/Qwen3.6-27B-MTP-GGUF | 27.3B | UD-Q6_K_XL | ≈ 39K |
218 models the site has analyzed fit on an RTX 5090 with at least 4K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 4090 — 24 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| bartowski/XYZAILab_XYZ-Aquila-mini-GGUF | 34.7B | Q4_K_M | ≈ 7K |
| unsloth/Qwen3.6-35B-A3B-MTP-GGUF | 35.5B | UD-Q4_K_S | ≈ 7K |
| peculiar-ragdoll/Cyber-Tiel-Coder-35B-A3B-GGUF-MTP | 35.5B | UD-Q4_K_S | ≈ 12K |
| HauhauCS/Qwen3.6-35B-A3B-Uncensored-HauhauCS-Aggressive | 34.7B | Q4_K_M | ≈ 18K |
| ornith-ai/Ornith-1.0-35B-GGUF | 34.7B | Q4_K_M | ≈ 18K |
| FINAL-Bench/POCKET-35B-GGUF | 34.7B | Q4_K_M | ≈ 18K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | Q5_K_S | ≈ 5K |
| bartowski/endless-frontier_BigBang-v1-GGUF | 35.5B | Q4_K_S | ≈ 22K |
| 0bserverx/Qwen3.8-27B-Heretic-Abliterated-Uncensored-GGUF | 26.9B | RVN-Q5_K_M-multilingual-vision | ≈ 6K |
| cyankiwi/Qwen3.8-27B-AWQ-INT4 | 27.8B | As published | ≈ 6K |
213 models the site has analyzed fit on an RTX 4090 with at least 4K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 3090 — 24 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| bartowski/XYZAILab_XYZ-Aquila-mini-GGUF | 34.7B | Q4_K_M | ≈ 7K |
| unsloth/Qwen3.6-35B-A3B-MTP-GGUF | 35.5B | UD-Q4_K_S | ≈ 7K |
| peculiar-ragdoll/Cyber-Tiel-Coder-35B-A3B-GGUF-MTP | 35.5B | UD-Q4_K_S | ≈ 12K |
| HauhauCS/Qwen3.6-35B-A3B-Uncensored-HauhauCS-Aggressive | 34.7B | Q4_K_M | ≈ 18K |
| ornith-ai/Ornith-1.0-35B-GGUF | 34.7B | Q4_K_M | ≈ 18K |
| FINAL-Bench/POCKET-35B-GGUF | 34.7B | Q4_K_M | ≈ 18K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | Q5_K_S | ≈ 5K |
| bartowski/endless-frontier_BigBang-v1-GGUF | 35.5B | Q4_K_S | ≈ 22K |
| 0bserverx/Qwen3.8-27B-Heretic-Abliterated-Uncensored-GGUF | 26.9B | RVN-Q5_K_M-multilingual-vision | ≈ 6K |
| cyankiwi/Qwen3.8-27B-AWQ-INT4 | 27.8B | As published | ≈ 6K |
213 models the site has analyzed fit on an RTX 3090 with at least 4K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
RTX 5080 — 16 GB
| Model | Params | File that fits | Context |
|---|---|---|---|
| unsloth/Qwen3.6-35B-A3B-MTP-GGUF | 35.5B | UD-IQ3_XXS | ≈ 13K |
| empero-ai/Qwen3.8-35B-A3B-Distill-GGUF | 35.5B | Q2_K | ≈ 24K |
| unsloth/Qwen3.6-27B-MTP-GGUF | 27.3B | Q3_K_M | ≈ 6K |
| unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF | 30.5B | UD-Q3_K_XL | ≈ 6K |
| openai/gpt-oss-20b | 20.9B | As published | ≈ 25K |
| 0bserverx/Qwen3.8-27B-Heretic-Abliterated-Uncensored-GGUF | 26.9B | RVN-Q3_K_M-multilingual-mtp | ≈ 7K |
| unsloth/Qwen3.6-35B-A3B-GGUF | 34.7B | UD-IQ3_S | ≈ 31K |
| ukisai/Swift-Qwen3.8-27B-GGUF | 27.3B | Q3_K_M | ≈ 9K |
| peculiar-ragdoll/Cyber-Tiel-Coder-35B-A3B-GGUF-MTP | 35.5B | UD-IQ3_XXS | ≈ 35K |
| unsloth/Qwen3.6-27B-GGUF | 26.9B | Q3_K_M | ≈ 10K |
150 models the site has analyzed fit on an RTX 5080 with at least 4K tokens of context; the 10 most downloaded are shown. See them all in the hardware calculator.
Why mixture-of-experts models get so far
A 35B mixture-of-experts model holds all 35B parameters in memory but only runs a few billion of them for each
token, so it behaves like a much smaller model while thinking, and like a large one in your VRAM. That is why the
lists above are full of 35B-A3B names: 35 billion parameters, about 3 billion active per token.
The consequence is that memory, not speed, is what stops you. A card that can hold the file will usually run it at a reasonable pace.
Related
- The most downloaded AI models that fit on your GPU
- The largest open-weight AI models, by parameter count
- Best AI models for a 24 GB GPU (RTX 4090, RTX 3090)
- Which AI models can I run on my GPU? — every card, including Macs and data-centre GPUs